Key Takeaways: AutoResearchClaw turns a single research idea into a fully drafted, data‑driven LaTeX paper by running a 23‑stage autonomous pipeline for literature, experiments, analysis, and writing.
What is AutoResearchClaw?
AutoResearchClaw is AIMING Lab’s open‑source, fully autonomous research pipeline that moves from “chat an idea” to “get a paper” with minimal human intervention. It is built as a 23‑stage state machine driven by LLM calls and experiment tooling, covering everything from literature collection and hypothesis generation through experiment execution, statistical analysis, paper drafting, simulated peer review, and final export.
The project is OpenClaw‑compatible: you can install AutoResearchClaw as a service in an OpenClaw assistant stack and trigger full research runs from chat channels like WhatsApp, Telegram, Slack, or Discord, or you can run it standalone via a command‑line interface and Python API.
You can explore AutoResearchClaw here:
- GitHub repo: https://github.com/aiming-lab/AutoResearchClaw
Why AutoResearchClaw matters
Most AI‑assisted research tools either summarize existing papers or generate speculative text without grounding it in actual experiments. AutoResearchClaw is designed specifically to break out of that pattern.
Key reasons it matters:
- End‑to‑end, not just text: The pipeline designs and runs experiments, validates and executes generated code, performs statistical analysis, and uses real metrics to drive the paper draft.
- Gate stages and rollback: Critical stages like literature screening, experiment design, and quality gating are explicit “gate” points with approvals and rollback rules, making the process more robust than a simple linear script.
- Citation verification: A dedicated citation verification stage cross‑checks references against multiple sources to reduce hallucinated or inconsistent citations.
- Self‑evolving behavior: Cross‑run memory and lesson extraction let the system improve its strategies over time instead of treating each run as disposable.
If you’re exploring agentic workflows, AI‑driven science, or automated literature review plus experiment orchestration, AutoResearchClaw is one of the most ambitious open‑source projects in this space.
Architecture overview: 23‑stage research pipeline
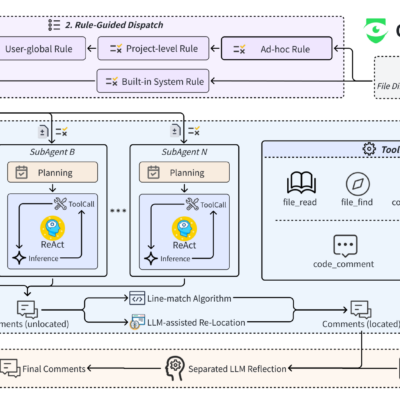
The heart of AutoResearchClaw is a 23‑stage pipeline grouped into eight phases, implemented as an IntEnum and executed by a dispatcher that calls stage‑specific executor functions.
Phase A: Research scoping
- TOPIC_INIT – Define the research question, scope, and constraints.
- PROBLEM_DECOMPOSE – Break the topic into sub‑problems and identify key variables.
Phase B: Literature discovery
- SEARCH_STRATEGY – Decide where and how to search (e.g., arXiv, Semantic Scholar) and verify data sources.
- LITERATURE_COLLECT – Execute the search and collect candidate papers.
- LITERATURE_SCREEN (gate) – Filter by relevance and quality; reject rolls back to Stage 4.
- KNOWLEDGE_EXTRACT – Turn papers into structured knowledge cards.
Phase C: Knowledge synthesis
- SYNTHESIS – Cluster topics, identify gaps, and summarize the state of the art.
- HYPOTHESIS_GEN – Generate falsifiable hypotheses aligned with gaps and constraints.
Phase D: Experiment design
- EXPERIMENT_DESIGN (gate) – Design an experiment protocol; reject rolls back to Stage 8.
- CODE_GENERATION – Generate experiment code with validation (AST checks, security scan, import checks).
- RESOURCE_PLANNING – Plan resources, scheduling, and dependency ordering.
Phase E: Experiment execution
- EXPERIMENT_RUN – Execute experiments in a sandbox, Docker, remote SSH, or simulated mode.
- ITERATIVE_REFINE – Run an edit→execute→evaluate loop to improve experiment quality.
Phase F: Analysis & decision
- RESULT_ANALYSIS – Perform statistical analysis and produce artifacts like
experiment_summary.jsonandresults_table.tex. - RESEARCH_DECISION – Decide to proceed, pivot, or iterate further based on outcomes.
Phase G: Paper writing
- PAPER_OUTLINE – Draft a structured outline targeted at venues like NeurIPS, ICML, or ICLR.
- PAPER_DRAFT – Write a full LaTeX draft using real experiment metrics.
- PEER_REVIEW – Run simulated peer review using multi‑agent evaluations.
- PAPER_REVISION – Revise the draft based on review feedback.
Phase H: Finalization
- QUALITY_GATE (gate) – Run automated quality scoring; reject rolls back to Stage 16.
- KNOWLEDGE_ARCHIVE – Archive findings, lessons learned, and cross‑run memory.
- EXPORT_PUBLISH – Generate charts, export final artifacts (e.g., LaTeX files, PDFs).
- CITATION_VERIFY – Cross‑check all citations against source data.
All of this is orchestrated by execute_pipeline() and execute_iterative_pipeline(), which manage state transitions, gate approvals, rollback, and artifact storage.
Requirements and configuration
AutoResearchClaw is implemented in Python and built to work with OpenAI‑compatible LLM APIs.
Key requirements:
- Python: 3.11+.
- Dependencies:
pyyaml,rich,matplotlib, and others declared inpyproject.tomlorrequirementssections. - LLM: Any OpenAI‑compatible API (tested with GPT‑4o, GPT‑5‑series models).
Configuration is handled via a YAML file—typically config.yaml based on an example template:
cp config.researchclaw.example.yaml config.yamlImportant sections in config.yaml include:
project.name/project.mode– Set project identity and mode.research.topic– The research question or idea the pipeline will explore.llm.base_url/llm.api_key/llm.primary_model– Your LLM provider endpoint and credentials.experiment.mode– One ofsimulated,sandbox,docker,ssh_remote, orcolab_drive.experiment.sandbox.python_path– Python interpreter path for sandbox execution.security.hitl_required_stages– Gate stages requiring human‑in‑the‑loop approval (default[5, 9, 20]).knowledge_base.root– Directory for knowledge base files and artifacts.
This config lets you choose how “hands‑off” the pipeline should be and how experiments are executed and validated.
Installing AutoResearchClaw
You can install AutoResearchClaw as a Python package and then interact with it via CLI or programmatic APIs.
Step 1: Clone the repository
git clone https://github.com/aiming-lab/AutoResearchClaw.git
cd AutoResearchClaw
Cloning gives you access to all docs, example configs, tests, and internal modules.
Step 2: Create and activate a virtual environment
It’s best to avoid polluting your global Python environment:
python3.11 -m venv .venv
source .venv/bin/activate   # macOS/Linux

# On Windows (PowerShell):
# .venv\Scripts\Activate.ps1
Step 3: Install AutoResearchClaw
Install in editable mode for easier development and inspection:
pip install -e .This registers the researchclaw CLI entrypoint and makes the researchclaw.* modules available in Python.
Step 4: Prepare configuration
Copy the example config template and edit it:
cp config.researchclaw.example.yaml config.yamlThen open config.yaml and set:
- Your
llm.base_url(e.g., OpenAI endpoint or compatible gateway). - Your
llm.api_key. - A
llm.primary_modelthat supports sufficient context for the pipeline. experiment.modetosandbox(default) or another mode that suits your environment.- A safe sandbox interpreter path (
experiment.sandbox.python_path) if you plan to execute generated code locally.
Finally, validate the config:
researchclaw validate --config config.yamlQuickstart: Running a fully autonomous research pipeline
With AutoResearchClaw installed and configured, you can launch a full pipeline run from the CLI.
Launch via CLI
researchclaw run \
  --topic "Few-shot reinforcement learning for battery health prediction" \
  --auto-approve
This does the following:
- Uses your
config.yamlfor LLM, experiment mode, and safety settings. - Starts at Stage 1 (TOPIC_INIT) and progresses through all 23 stages.
- Automatically approves gate stages, meaning it will not stop for manual review at literature screening, experiment design, or quality gate.
Artifacts (knowledge base markdown files, experiment code, charts, LaTeX drafts, final paper exports) are stored in a run directory under the configured knowledge base root or an artifacts/ folder.
Run programmatically via Python
If you prefer more control or want to integrate AutoResearchClaw into a larger application, use the Python API:
from pathlib import Path
from researchclaw.pipeline.runner import execute_pipeline
from researchclaw.config import RCConfig
from researchclaw.adapters import AdapterBundle

config = RCConfig.load("config.yaml", check_paths=False)

results = execute_pipeline(
    run_dir=Path("artifacts/my-run"),
    run_id="demo-001",
    config=config,
    adapters=AdapterBundle(),
    auto_approve_gates=True,
)
Here:
run_diris where artifacts will be stored.run_ididentifies this specific run.AdapterBundleprovides hooks for notifications or OpenClaw integration.
You can swap execute_pipeline for execute_iterative_pipeline() when you want iterative control over stages (e.g., for targeted interventions or human‑in‑the‑loop experimentation).
Execution modes and experiment safety
The experiment subsystem is deliberately cautious: it validates and executes generated code in controlled environments.
Key components:
- ExperimentSandbox: Manages local subprocess execution with boundaries for code, imports, and resources.
- ExperimentRunner: Orchestrates runs, logging outputs and errors.
- ExperimentGitManager: Packs experiments into git repos for reproducibility and rollback.
- Validator: Runs AST parsing, security scans, and import checks, auto‑repairing code where possible before execution.
- Visualize: Generates charts (trajectories, comparisons, timelines, iteration plots) using matplotlib.
Experiment modes allow you to choose where code runs:
simulated– No real execution; useful for dry runs or environment testing.sandbox– Local execution via a designated Python interpreter.docker– Execution inside Docker containers for isolation.ssh_remote– Remote execution via SSH on dedicated compute nodes.colab_drive– Cloud‑assisted runs using external notebooks and storage.
Security constraints and gate stages can be configured in config.yaml, including which stages demand human approval (security.hitl_required_stages).
Integrating AutoResearchClaw with coding agents and OpenClaw
AutoResearchClaw is designed to pair with coding agents and assistant frameworks.
- OpenClaw integration: The adapters layer can connect AutoResearchClaw to OpenClaw, an assistant framework that operates across messaging platforms. Once configured, you can trigger research runs by sending a single chat message, with progress and artifacts surfaced back to chat.
- Coding agent skills: Projects like
researchclaw-skilldemonstrate how to plug AutoResearchClaw into existing coding agents, turning them into “research‑capable” tools that can launch pipelines and monitor their progress.
Best practices and caveats
AutoResearchClaw is powerful, but you should treat it as a tool that complements human judgment, not replaces it.
Some practical guidelines:
- Start with simulated or sandbox mode: Before running complex experiments, verify that your configuration, code validation, and environment boundaries behave as expected in safer modes.
- Review gate stages: Even with
--auto-approve, occasionally run with manual gate approvals to inspect literature screening decisions, experiment designs, and quality gate outputs. - Check citations and metrics: Use the exported
experiment_summary.json,results_table.tex, and citation verification logs to ensure the pipeline’s claims align with your understanding of the domain. - Align with venue policies: AutoResearchClaw can target specific venues (NeurIPS, ICML, ICLR), but you are responsible for upholding originality, ethics, and author contribution norms.
When used thoughtfully, AutoResearchClaw can dramatically accelerate exploratory research, help structure complex projects, and serve as a powerful collaborator in agent‑driven scientific workflows—especially for solo researchers and small teams looking to punch above their weight.